Vector similarity measures and scoring
Explore vector similarity measures and scoring in Elasticsearch, including L1 & L2 distance, cosine similarity, dot product similarity and max inner product similarity.
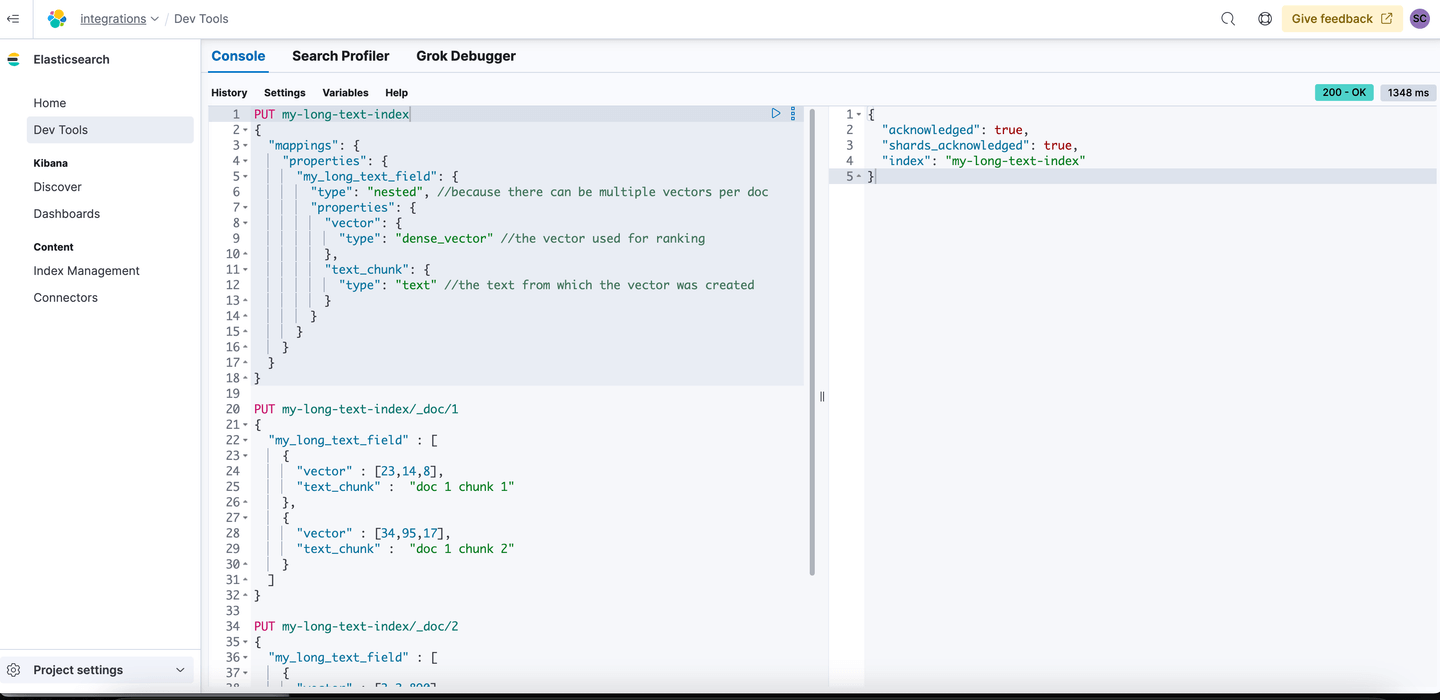
Retrieval of originating information in multi-vector documents
Learn about multi-vector documents in Elasticsearch, their use cases, and how to link original context to a multi-vector document.
Red Hat & Elastic: Red Hat OpenShift AI integration with Elasticsearch
Red Hat OpenShift users can now implement Elasticsearch for vector search & RAG applications via the Red Hat Ecosystem Catalog. Explore this integration here.
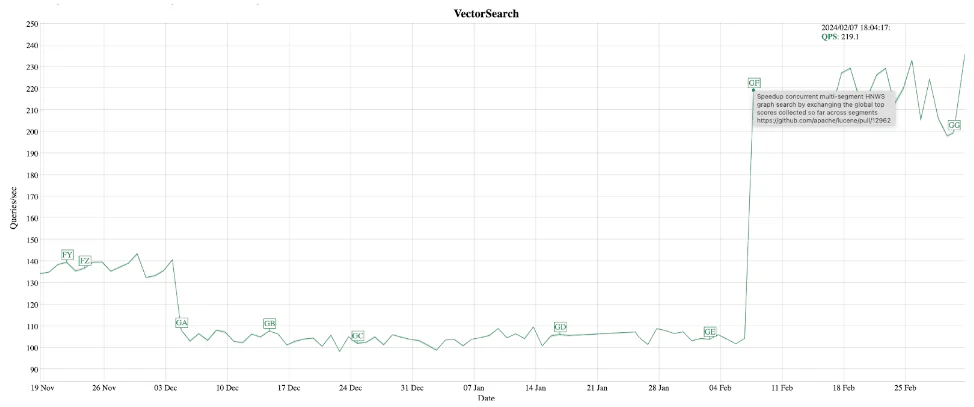
Making Elasticsearch and Lucene the best vector database: up to 8x faster and 32x efficient
Discover the recent enhancements and optimizations that notably improve vector search performance in Elasticsearch & Lucene vector database.
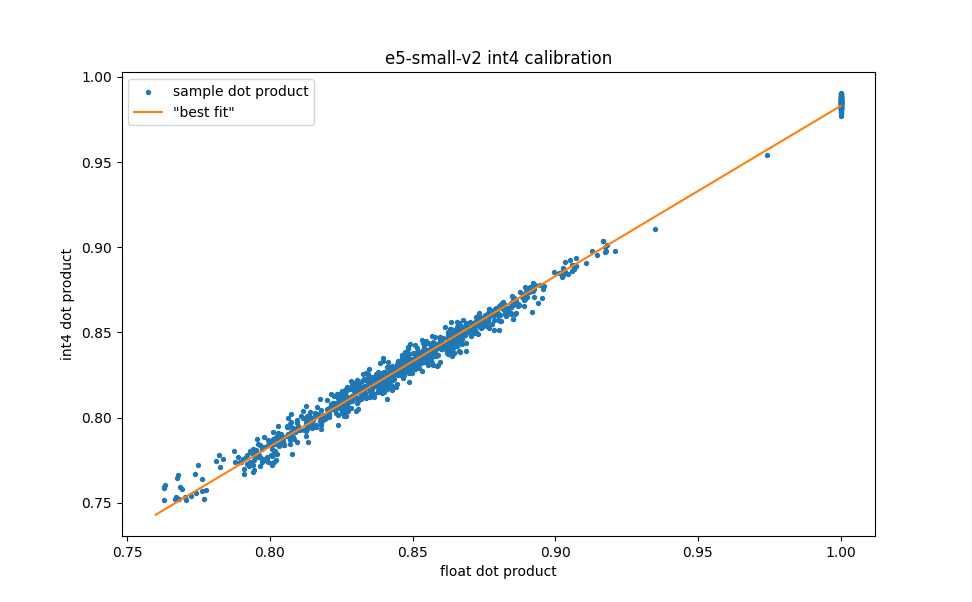
Scalar quantization optimized for vector databases
Optimizing scalar quantization for the vector database use case allows us to achieve significantly better performance for the same retrieval quality at high compression ratios.
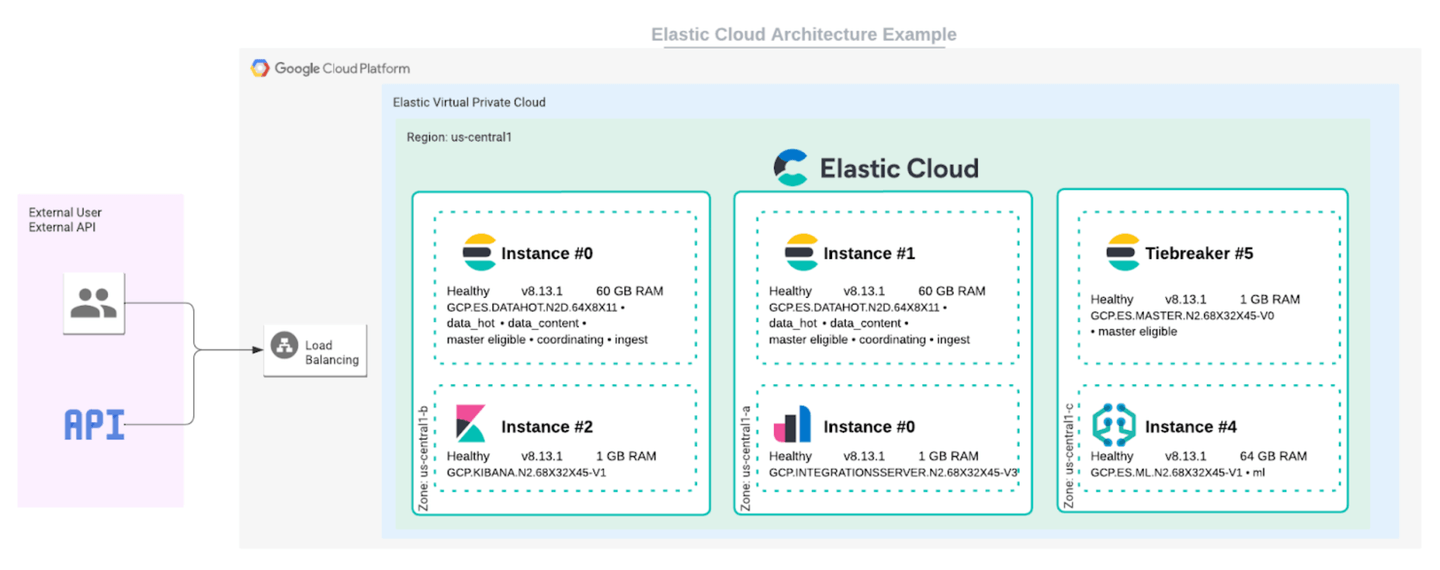
Elastic Cloud adds Elasticsearch Vector Database optimized instance to Google Cloud
Elasticsearch's vector search optimized profile for GCP is available. Learn more about it and how to use it in this blog.
Simplifying kNN search
Elastic's kNN search has evolved. This blog explains the simplification of kNN search, where k and num_candidates are now optional.
Elasticsearch open Inference API adds support for Cohere’s Rerank 3 model
“Learn about Cohere reranking, how to use Cohere's Rerank 3 model with the Elasticsearch open inference API and Elastic's roadmap for semantic reranking.”
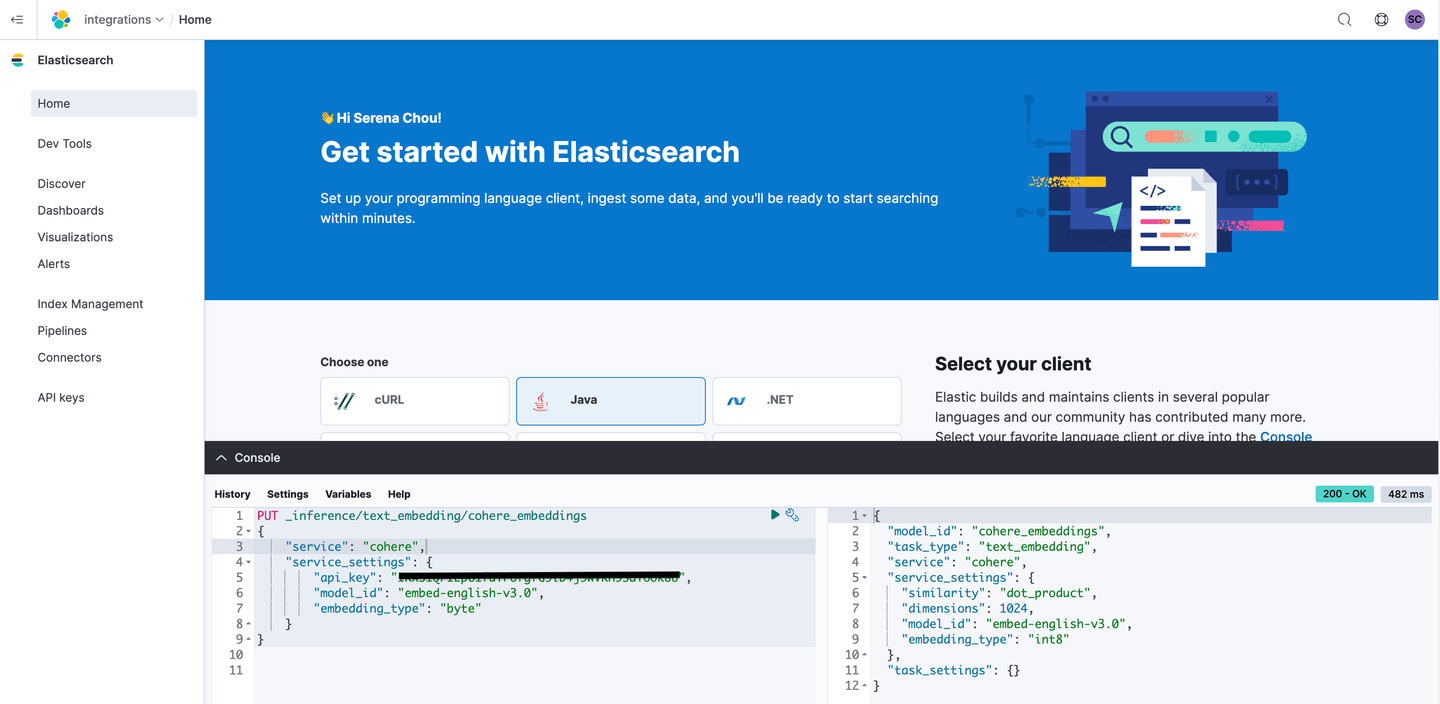
Using Cohere embeddings with Elastic-built search experiences
Elasticsearch now supports Cohere embeddings! This blog explains how to use Cohere embeddings with Elastic-built search experiences.
Scaling ML inference pipelines in Elasticsearch: How to avoid issues and troubleshoot bottlenecks
Learn strategies to run Machine Learning (ML) inference pipelines in Elasticsearch, troubleshoot bottlenecks and avoid issues when scaling.
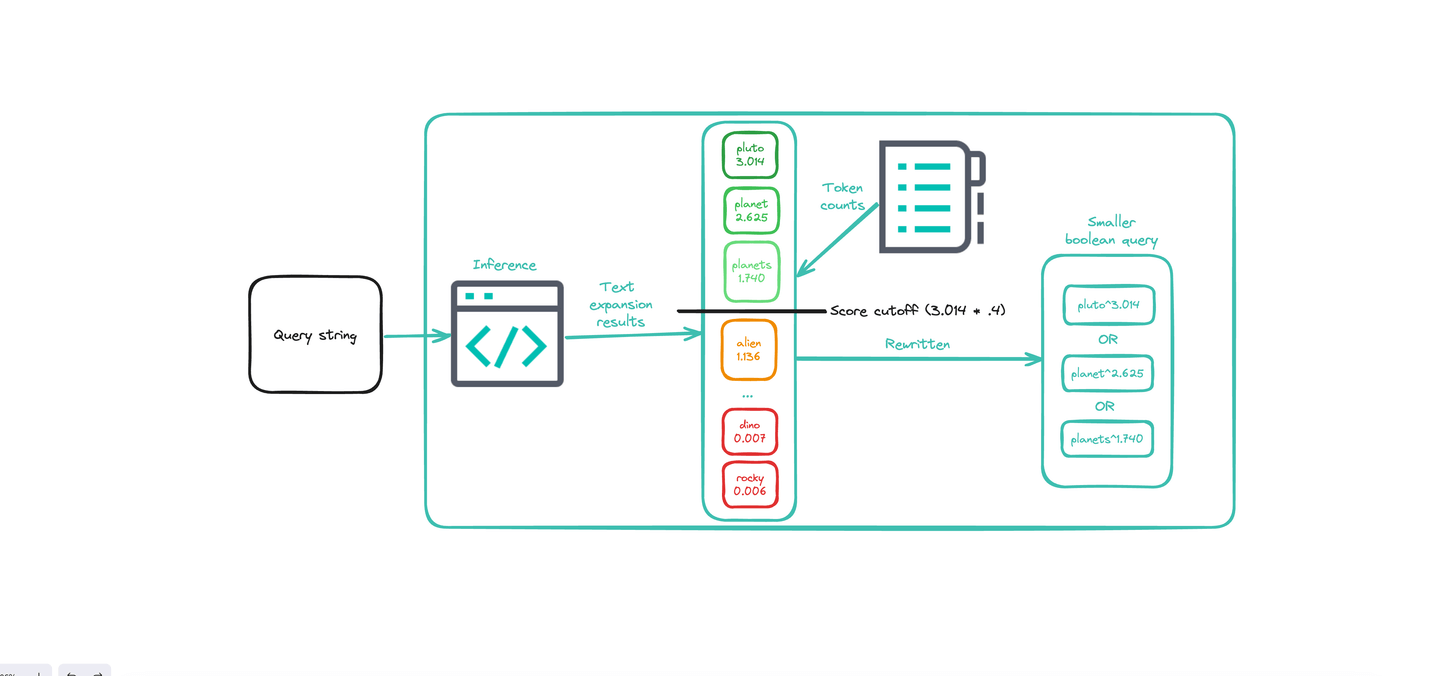
Improving text expansion performance using token pruning
Learn about token pruning and how it boosts the performance of text expansion queries by making them more efficient without sacrificing recall.
Semantic search as service at a search center of excellence
Learn how to implement and scale semantic search as a service for a search Center of Excellence (COE) using ELSER.