Blogs
Developer insights and practical how-to articles from our experts to inspire and empower your search experience.
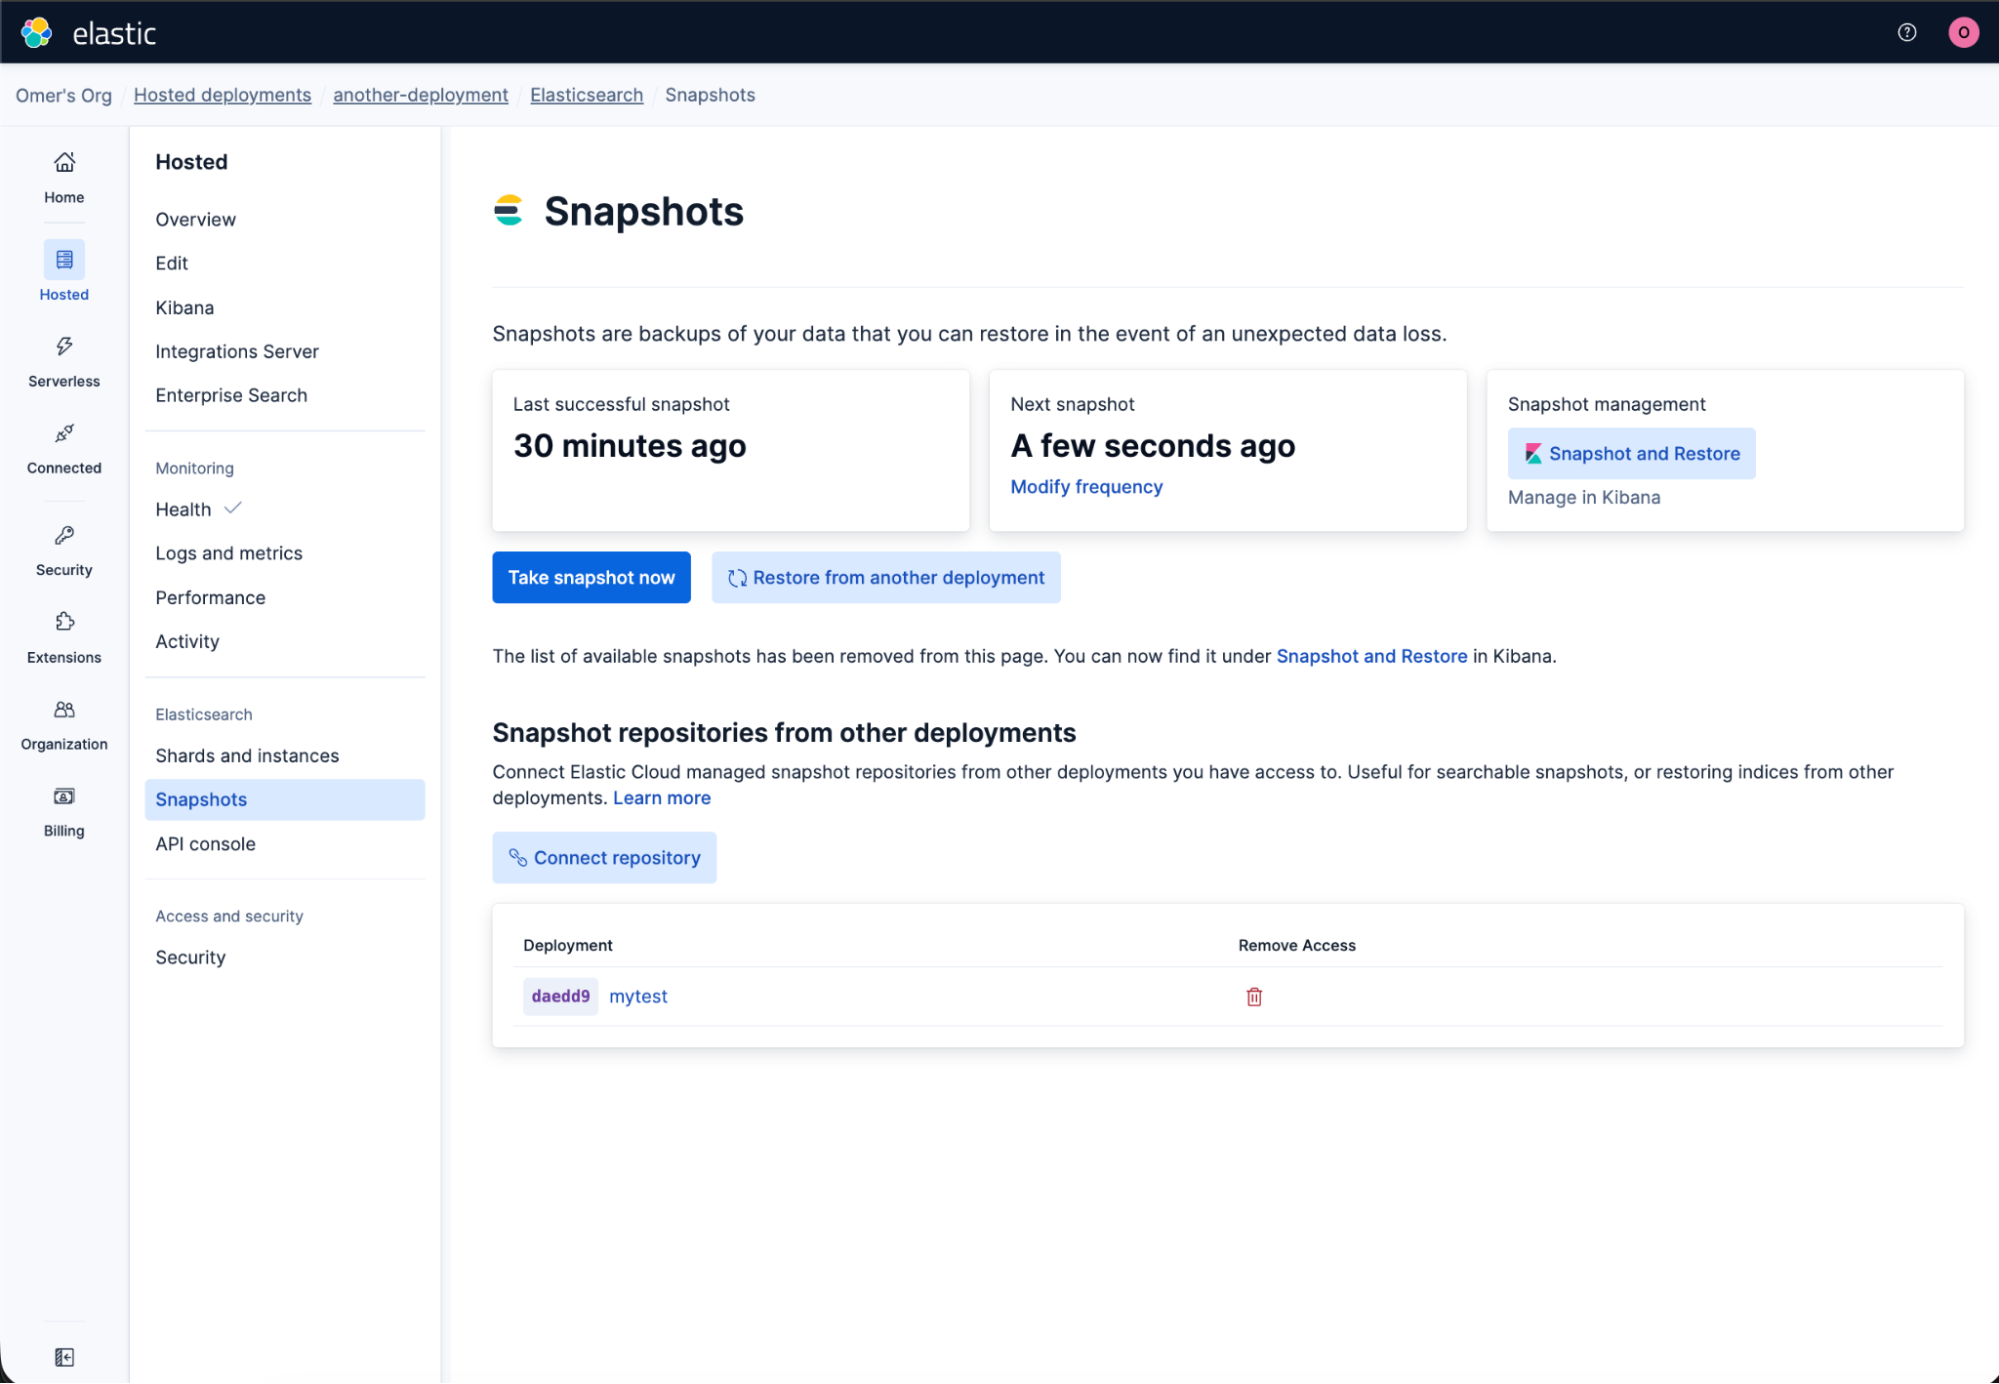
One API call per operation: how Elastic Cloud Hosted makes fleet-scale deployment management practical
Elastic Cloud Hosted adds five targeted APIs for upgrade, tier scaling, user settings, tags and snapshot repository linking, each replacing a multi-step deployment plan edit with a single focused call.
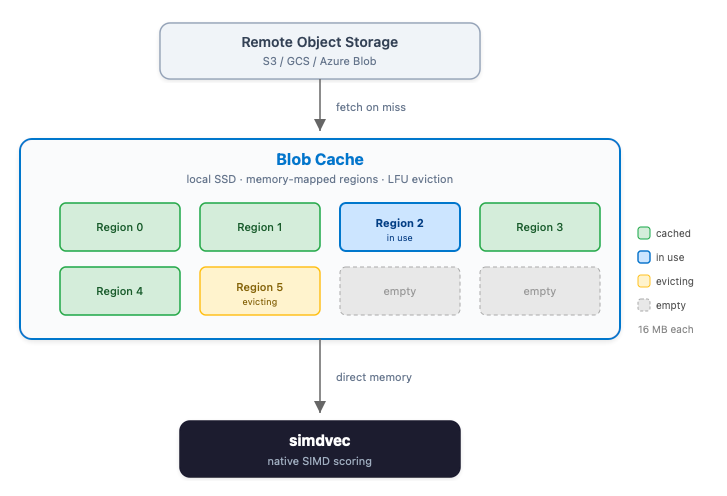
How we doubled vector search throughput on Elasticsearch Serverless
How we brought Elasticsearch's native SIMD scoring engine to serverless, and why serverless is where vector search innovation happens next.
How Elasticsearch cuts time-series storage by 34% with synthetic _id and bloom filters
Learn how synthetic _id uses bloom filters to cut time-series storage by 34% while maintaining full API compatibility.
Small model, big benchmarks: how Jina-VLM beat the competition at 2.4B and what ICLR told us is coming next
Jina-VLM is a 2.4B open multilingual VLM leading VQA benchmarks across 29 languages. Plus: five days of ICLR 2026 takeaways on RLVR, sparse embeddings and retrieval.
Cutting Elasticsearch DiskBBQ query quantization time by 5x
See how asymmetric quantization cuts DiskBBQ query quantization overhead from about 20% to 4% with little recall impact.
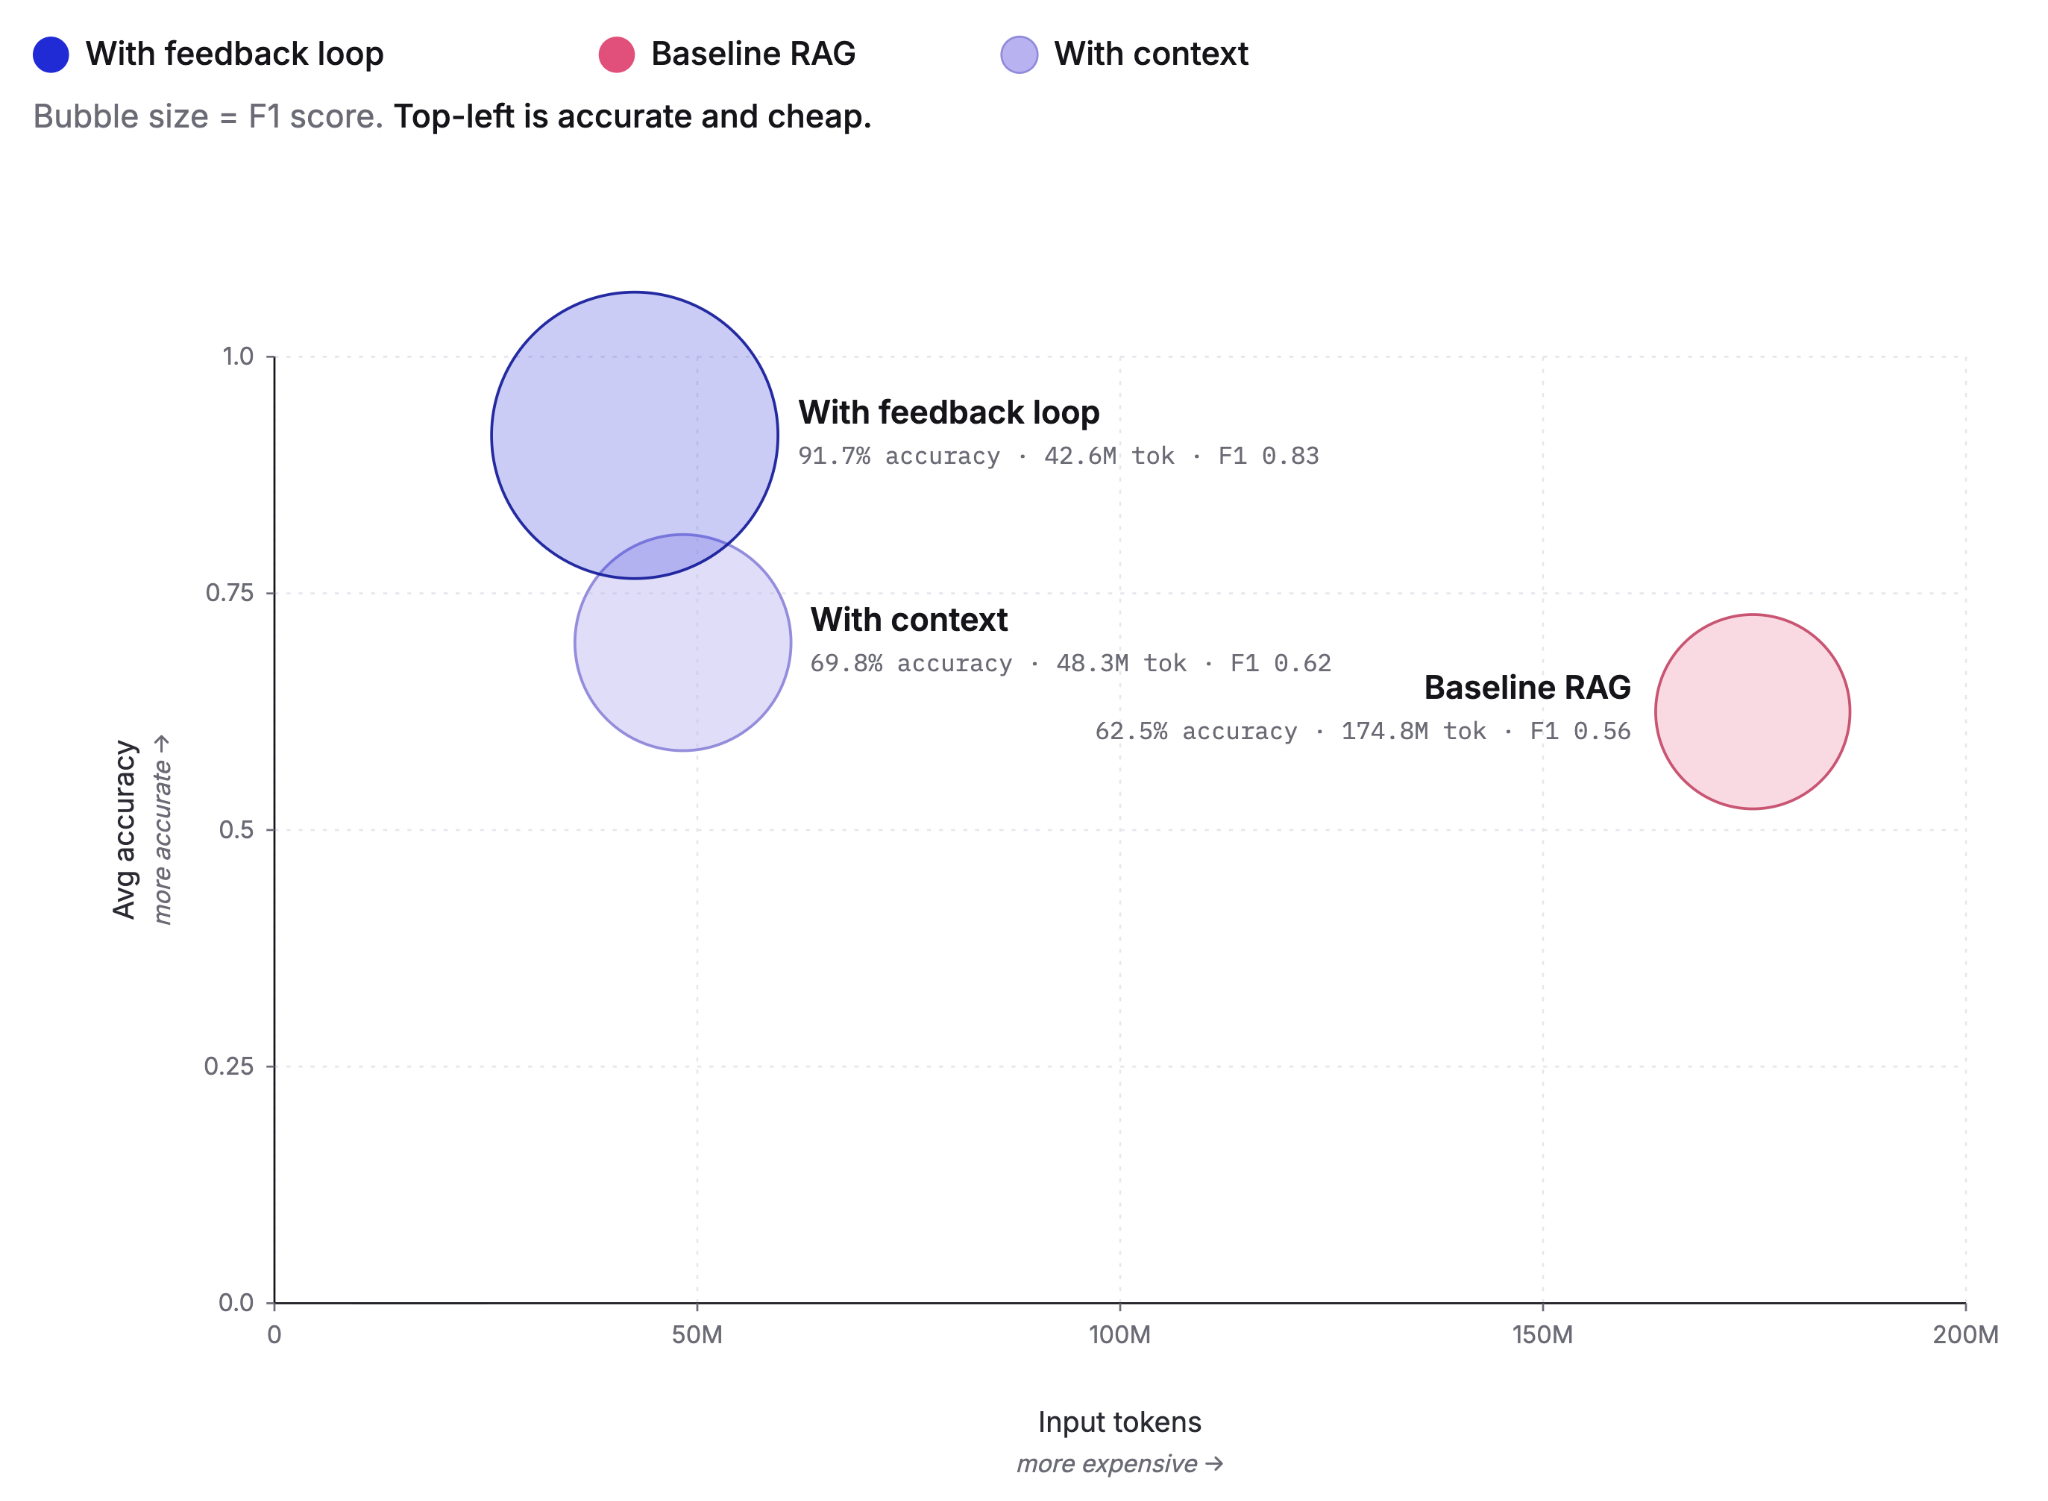
Cutting agent costs with pre-computed context
Pre-computing context as Knowledge Indicators reduces LLM agent token costs by up to 75% and improves answer accuracy from 60% to 92%. This post covers the extraction, retrieval and feedback loop that make it work, tested against the BrowseComp-Plus benchmark.
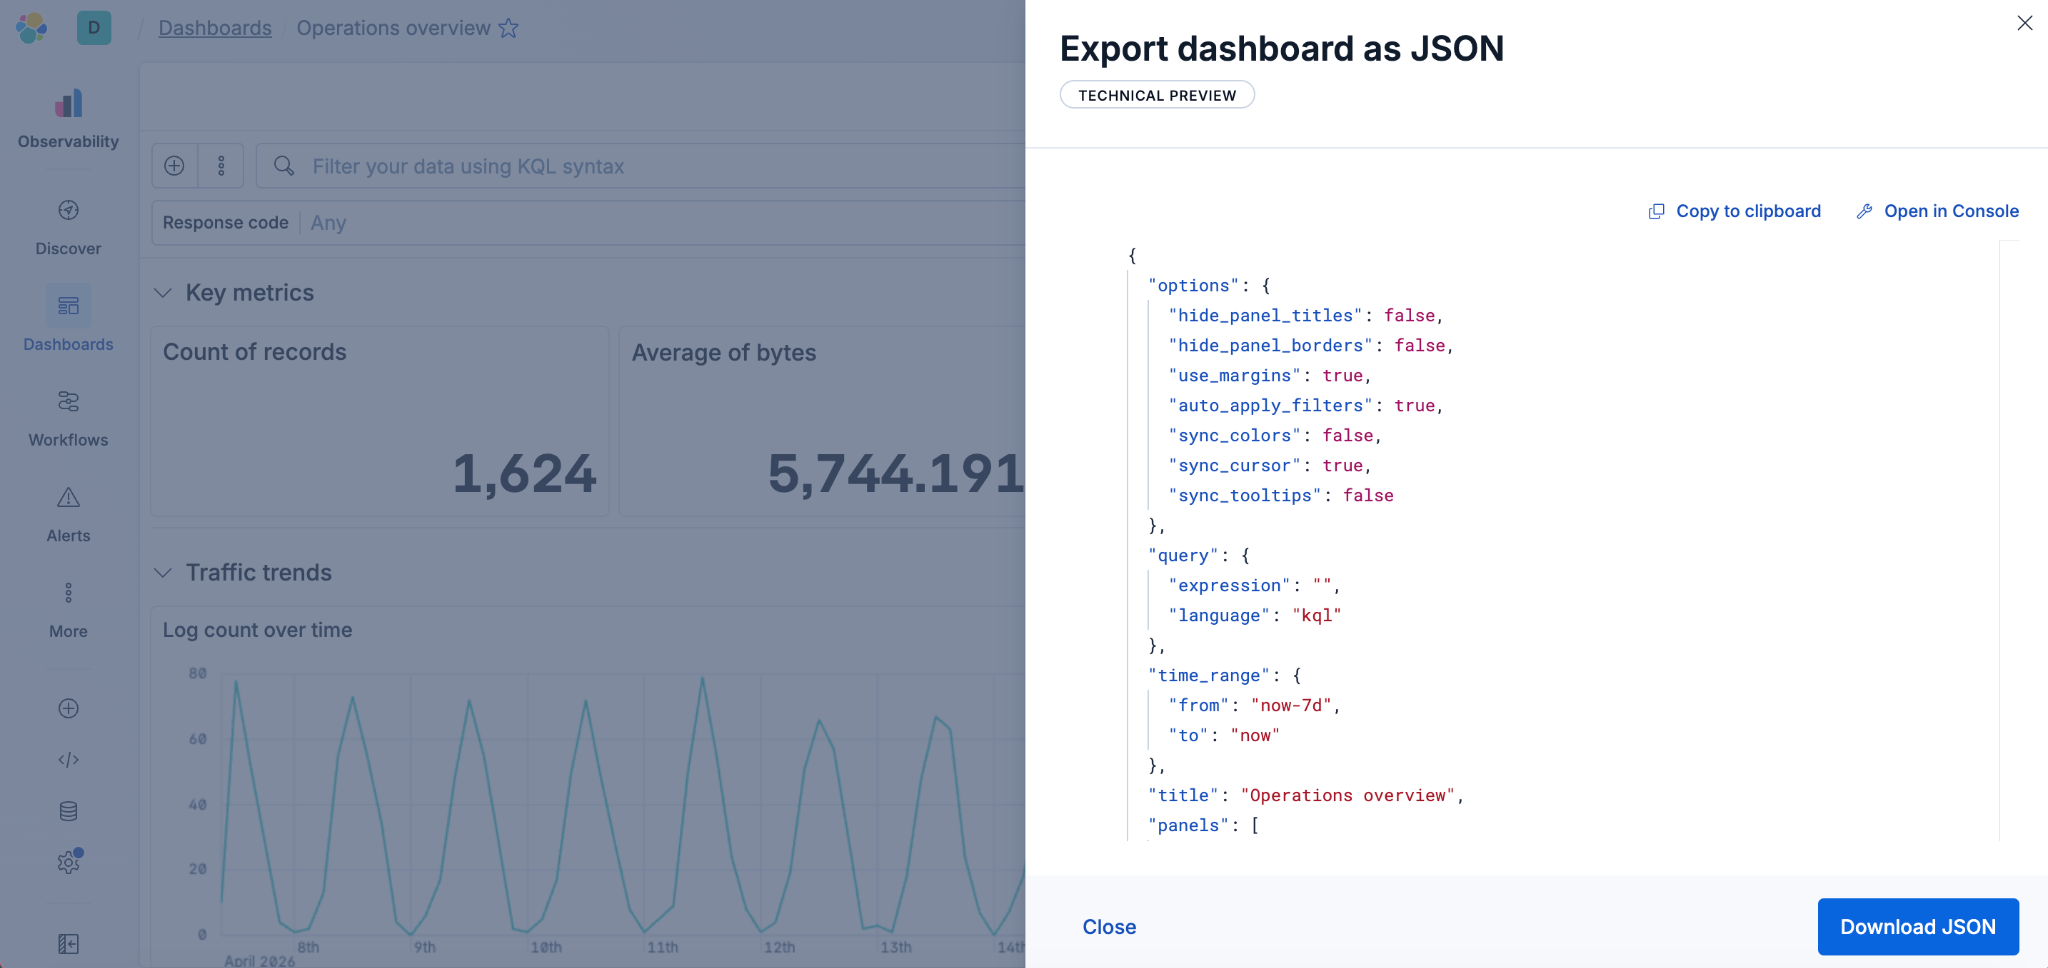
Kibana dashboards as code: GitOps, drift detection and Terraform for Kibana dashboards in Elastic 9.4
Elastic 9.4 ships a typed Dashboards API and a native Terraform resource that bring drift detection, PR-reviewable diffs and git-based rollback to Kibana dashboards for the first time.
AI Chat in Kibana now natively renders dashboards
The Elastic AI Chat in Kibana now builds dashboards from natural language, keeping your visuals and analysis in one thread and letting you save them as reusable Kibana objects.
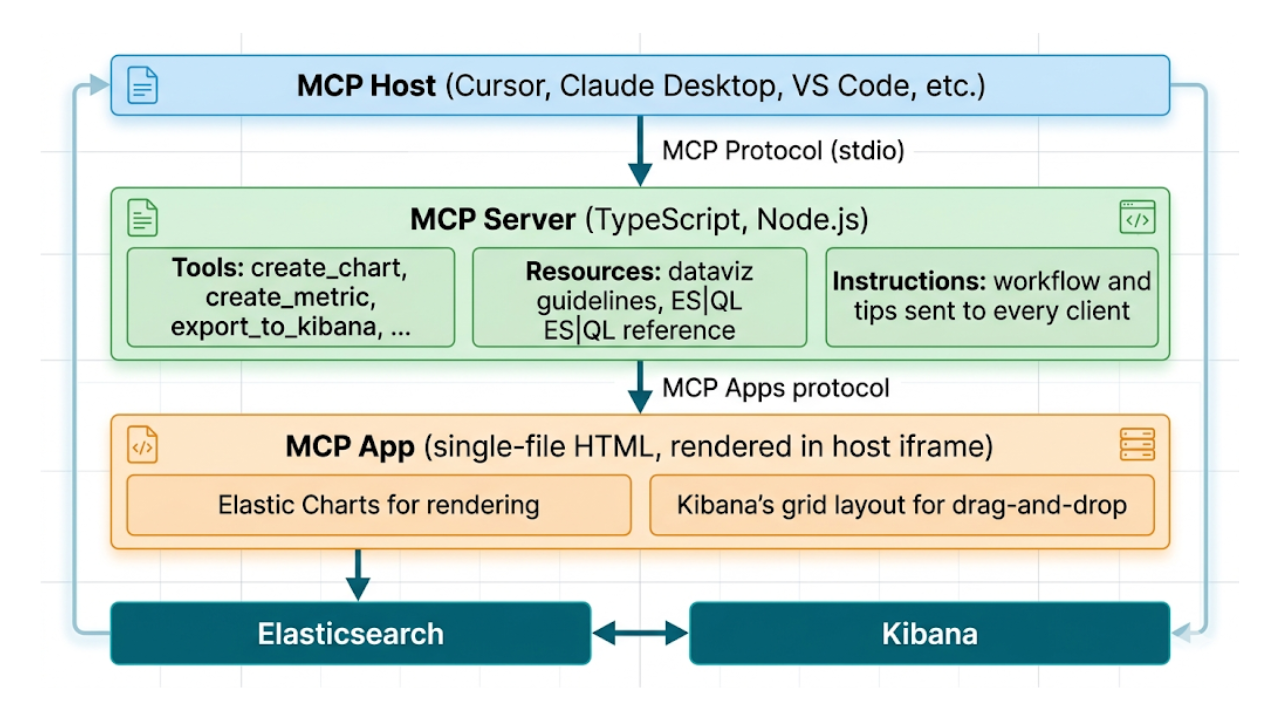
Describe it, don't draw it: AI-native Kibana dashboards via MCP and ES|QL
From prompt to dashboard. Learn how to build Kibana dashboards with natural language, using example-mcp-dashbuilder: an open source MCP application that writes ES|QL queries, creates interactive charts and exports fully functional dashboards directly to Kibana.
Up to 3x faster stored-vector queries in Elasticsearch
Elasticsearch 9.4 provides a simpler way to search with vectors stored in an Elasticsearch index, with up to 3x lower latency.
Elasticsearch downsampling methods: last-value vs. aggregate sampling
Elasticsearch downsampling now gives you a choice: last-value sampling for maximum storage savings or aggregate sampling for precise rate calculations and counter resets, both fully queryable in ES|QL.