Blogs
Developer insights and practical how-to articles from our experts to inspire and empower your search experience.
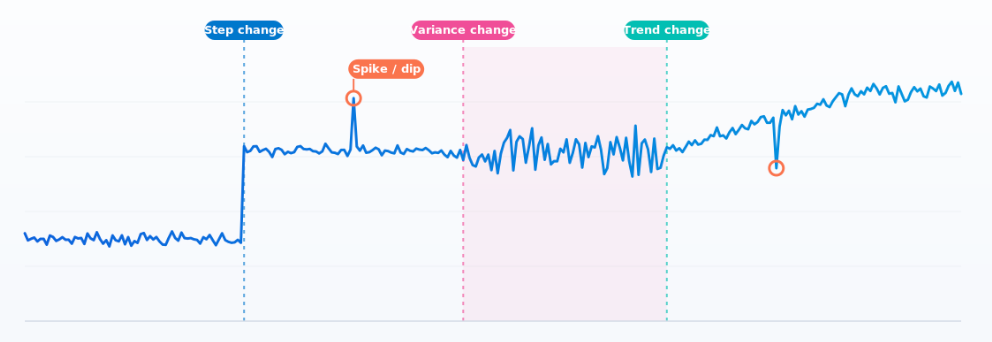
How Elasticsearch detects multiple change points in time series with 0.99 recall
ES|QL's CHANGE_POINT command finds structural shifts, variance changes and spikes in any metric in ~1ms, without tuning anything per series.
On-prem in under 5 minutes: Jina embedding models now available for on-prem deployment
All 28 Jina AI models, including rerankers, as ready-to-deploy Docker containers, with zero telemetry and no license server. Drop-in compatible with OpenAI, Cohere, Voyage AI and Elastic Inference Service APIs.
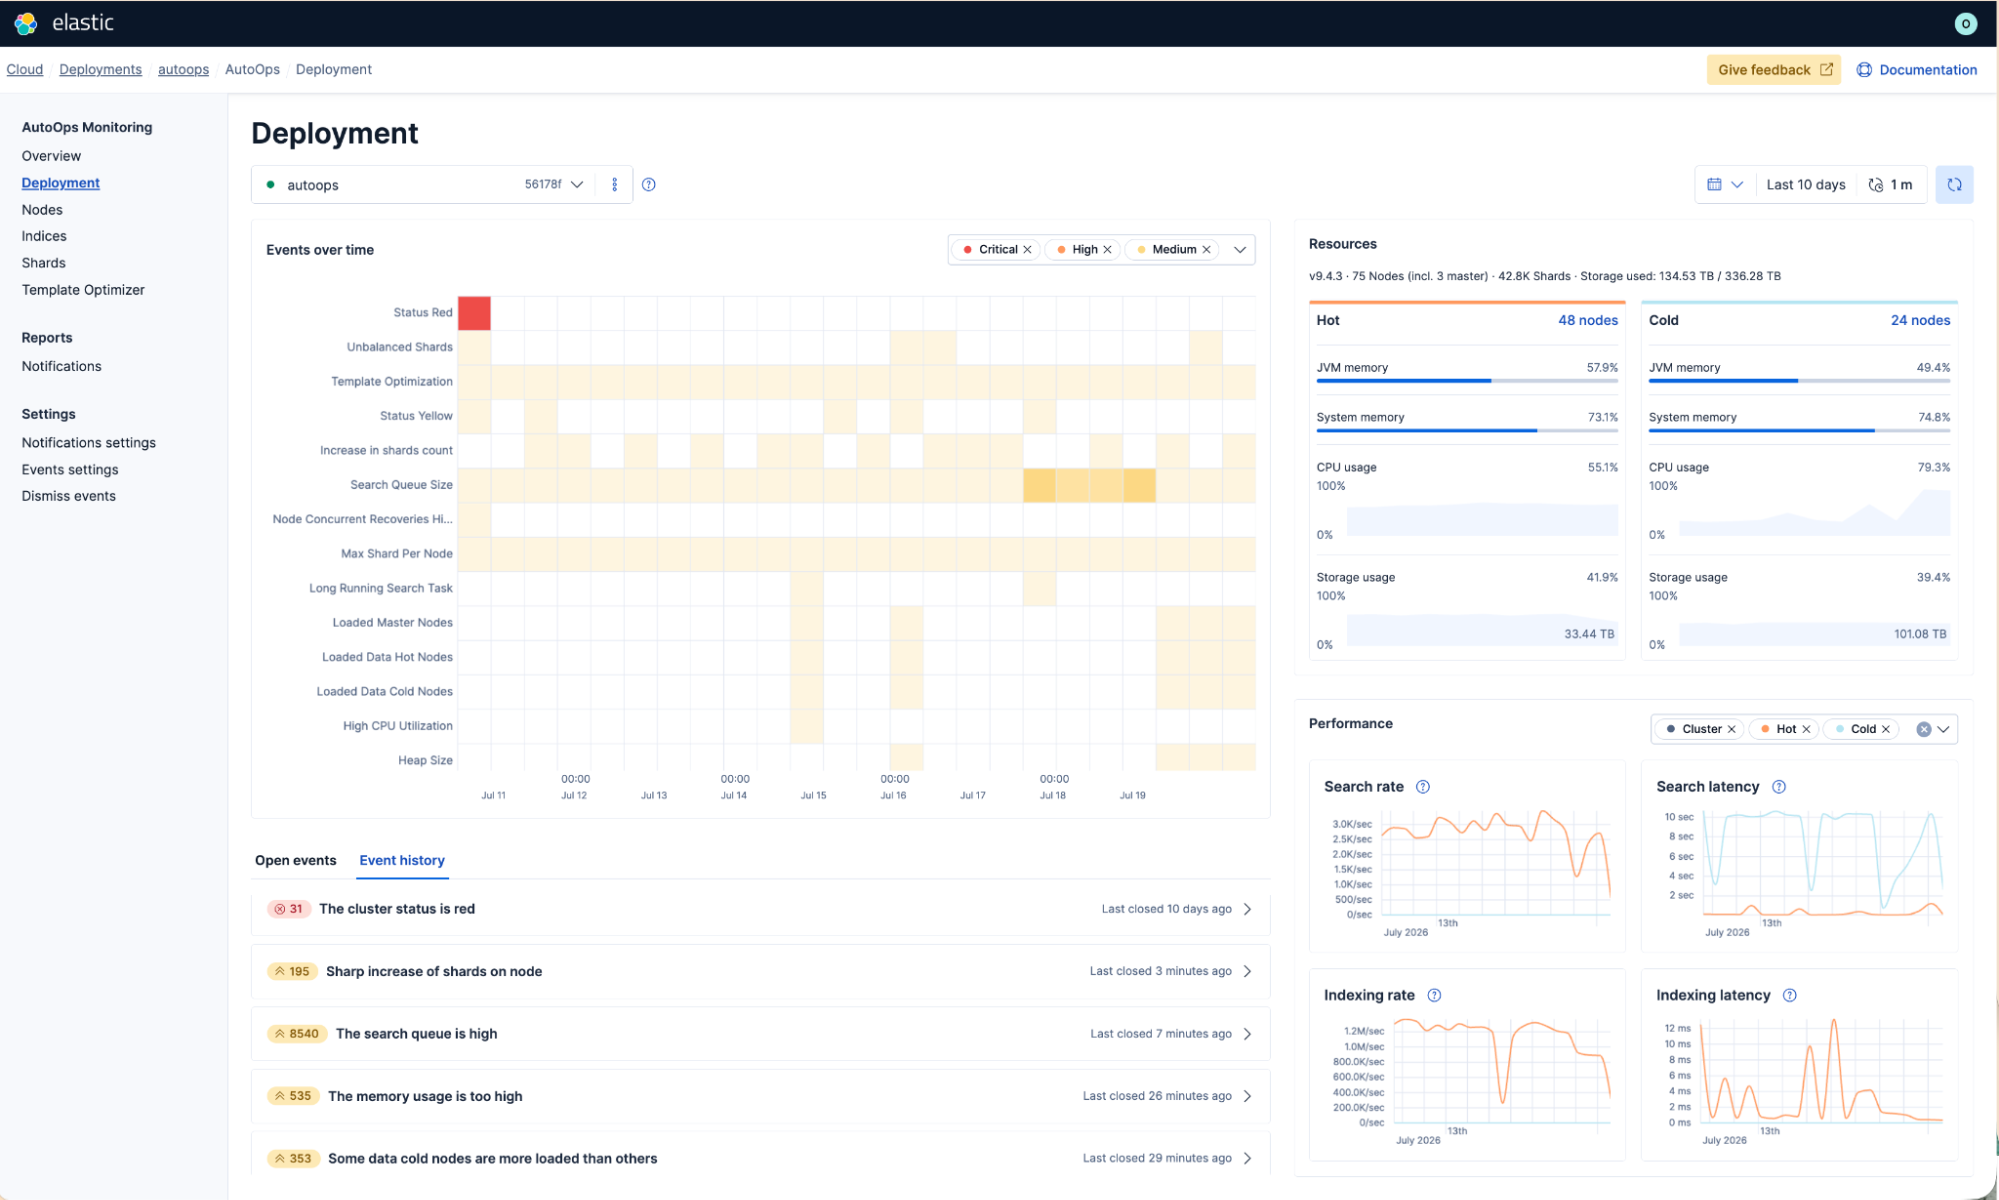
Faster Elasticsearch issue triage with redesigned AutoOps
AutoOps introduces clearer severity, updated page layouts, and simpler issue triage for Elastic Cloud Hosted deployments and Cloud Connect clusters.
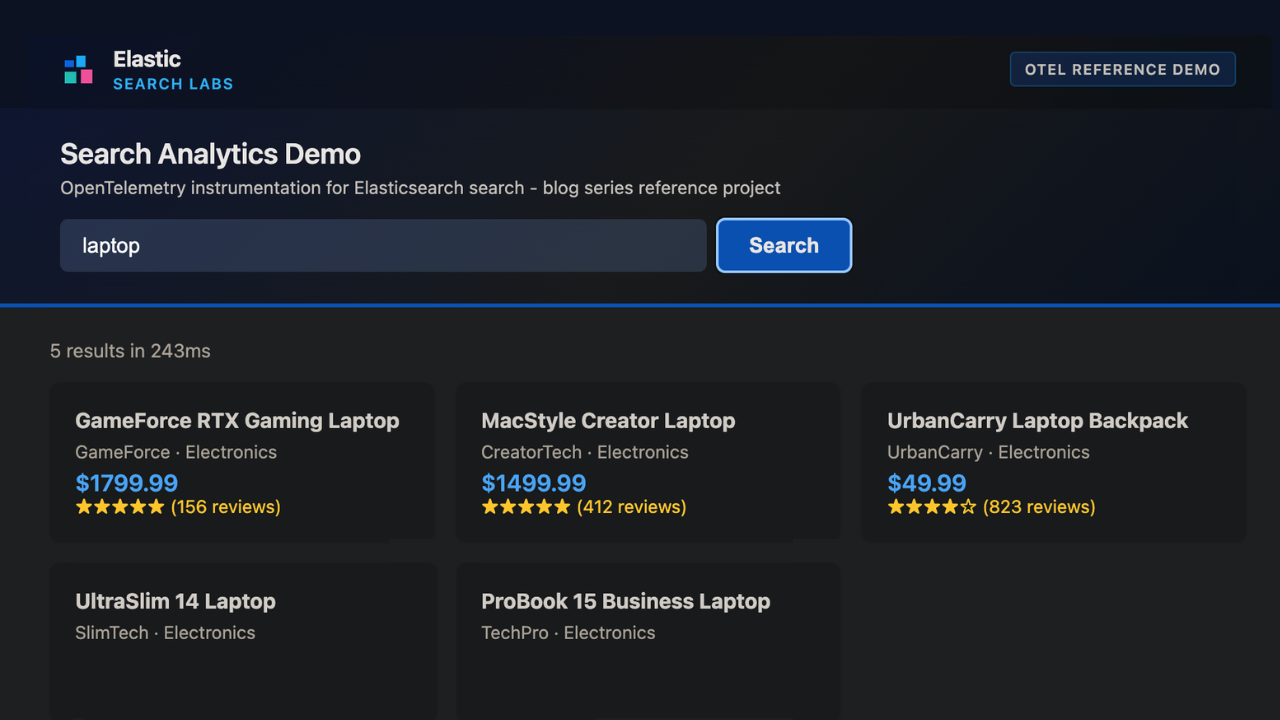
How to instrument your search API with OpenTelemetry and query it with ES|QL
Add custom attributes to OpenTelemetry spans and run six ES|QL queries that reveal your top searches, zero-result rate and slowest queries.
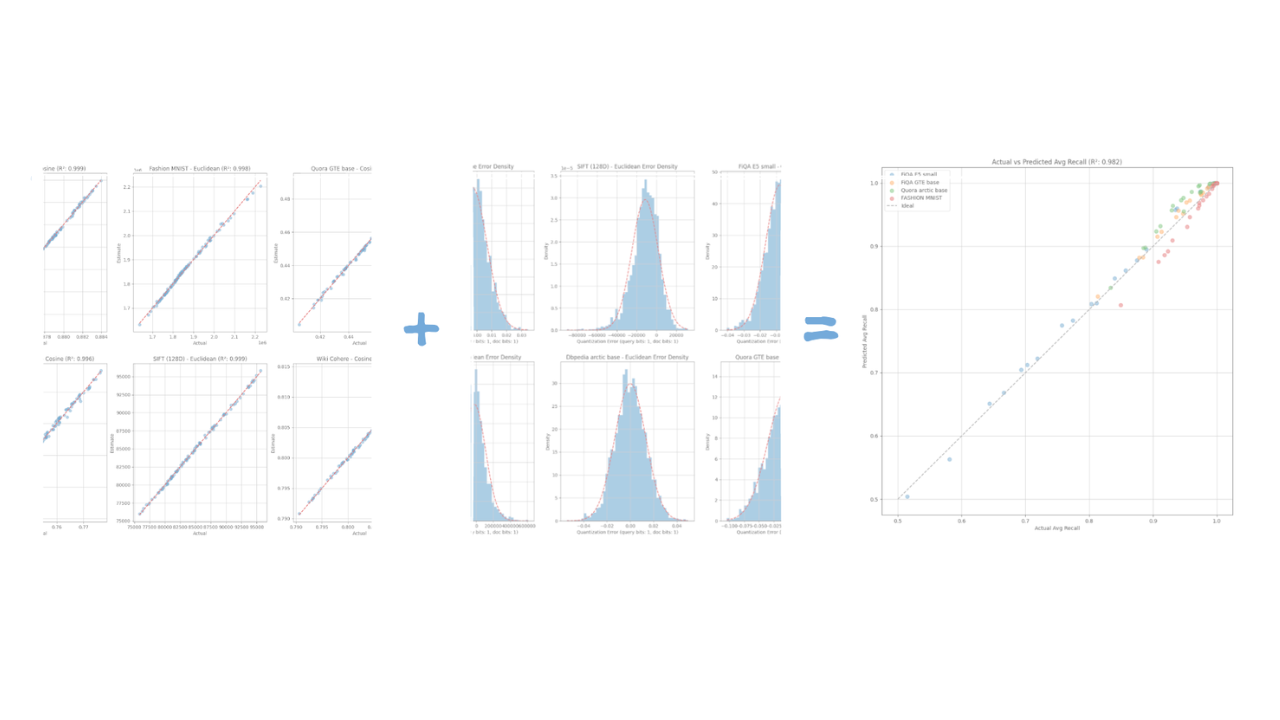
How Elasticsearch auto-tunes vector quantization to hit your recall target
Learn the geometric model that lets Elasticsearch predict recall with R² > 0.98 accuracy and auto-select vector quantization parameters from a small data sample.
4 NVIDIA AI tasks, 1 Elasticsearch API: Embeddings, chat, completion, and rerank
Set up NVIDIA hosted models in Elasticsearch with one API key and a model ID. No custom integration code needed.
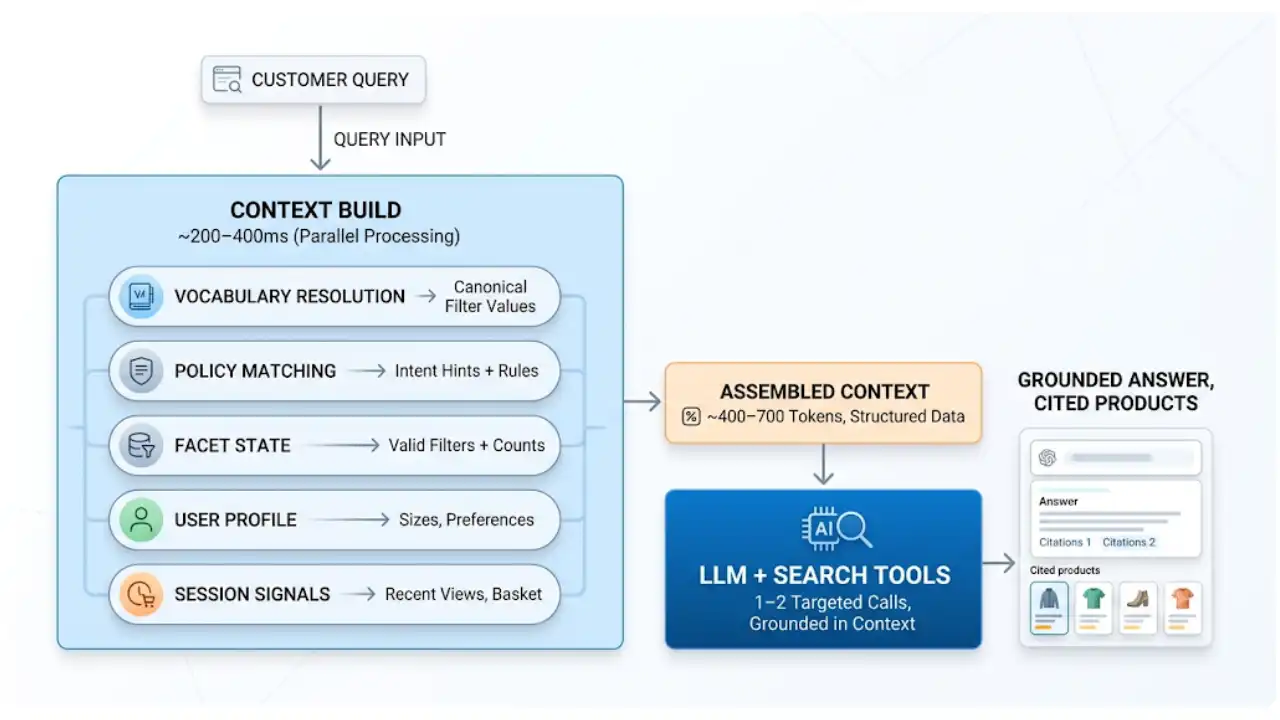
AI shopping agents: Why context comes before the query
AI shopping agents that guess at your vocabulary make expensive mistakes. Pre-computed catalog context stops the guessing before the first tool call.
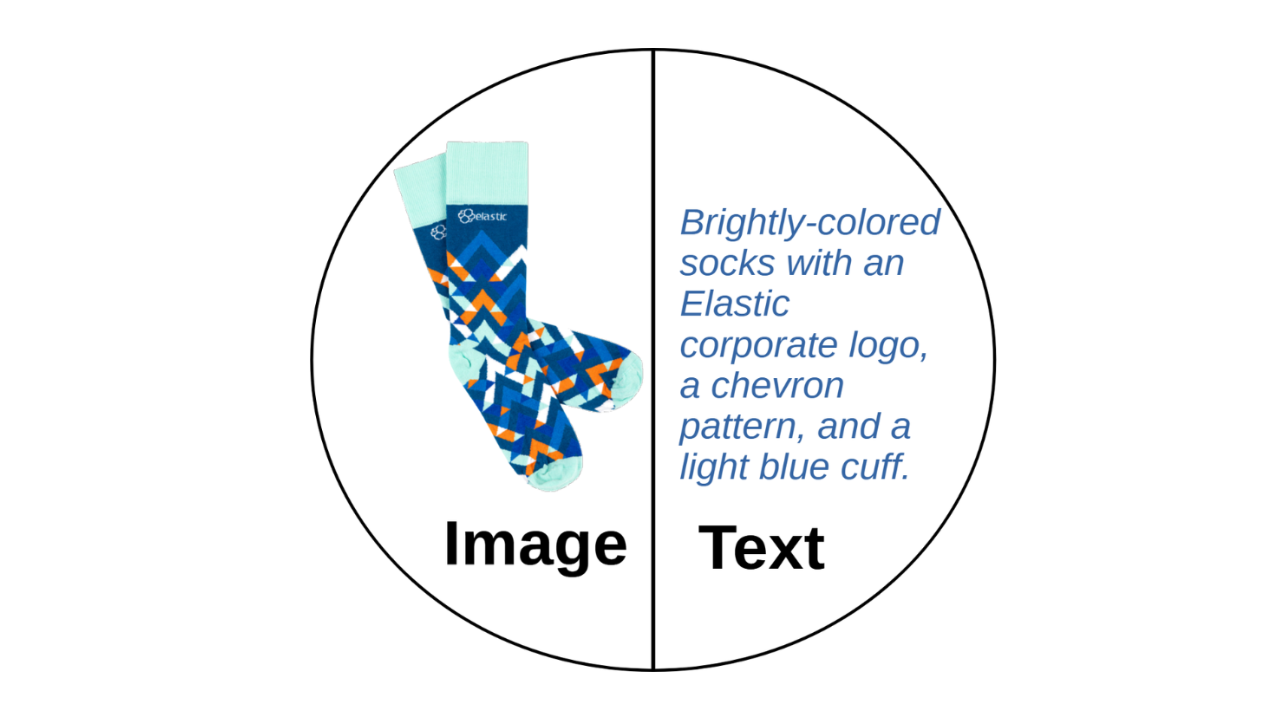
A picture is worth 1.5x the words: What we learned benchmarking product search embeddings
We benchmarked two embedding models on 5,000 real products and found that combining image and text beats either alone by up to 50%. Here's the data and the model that won.
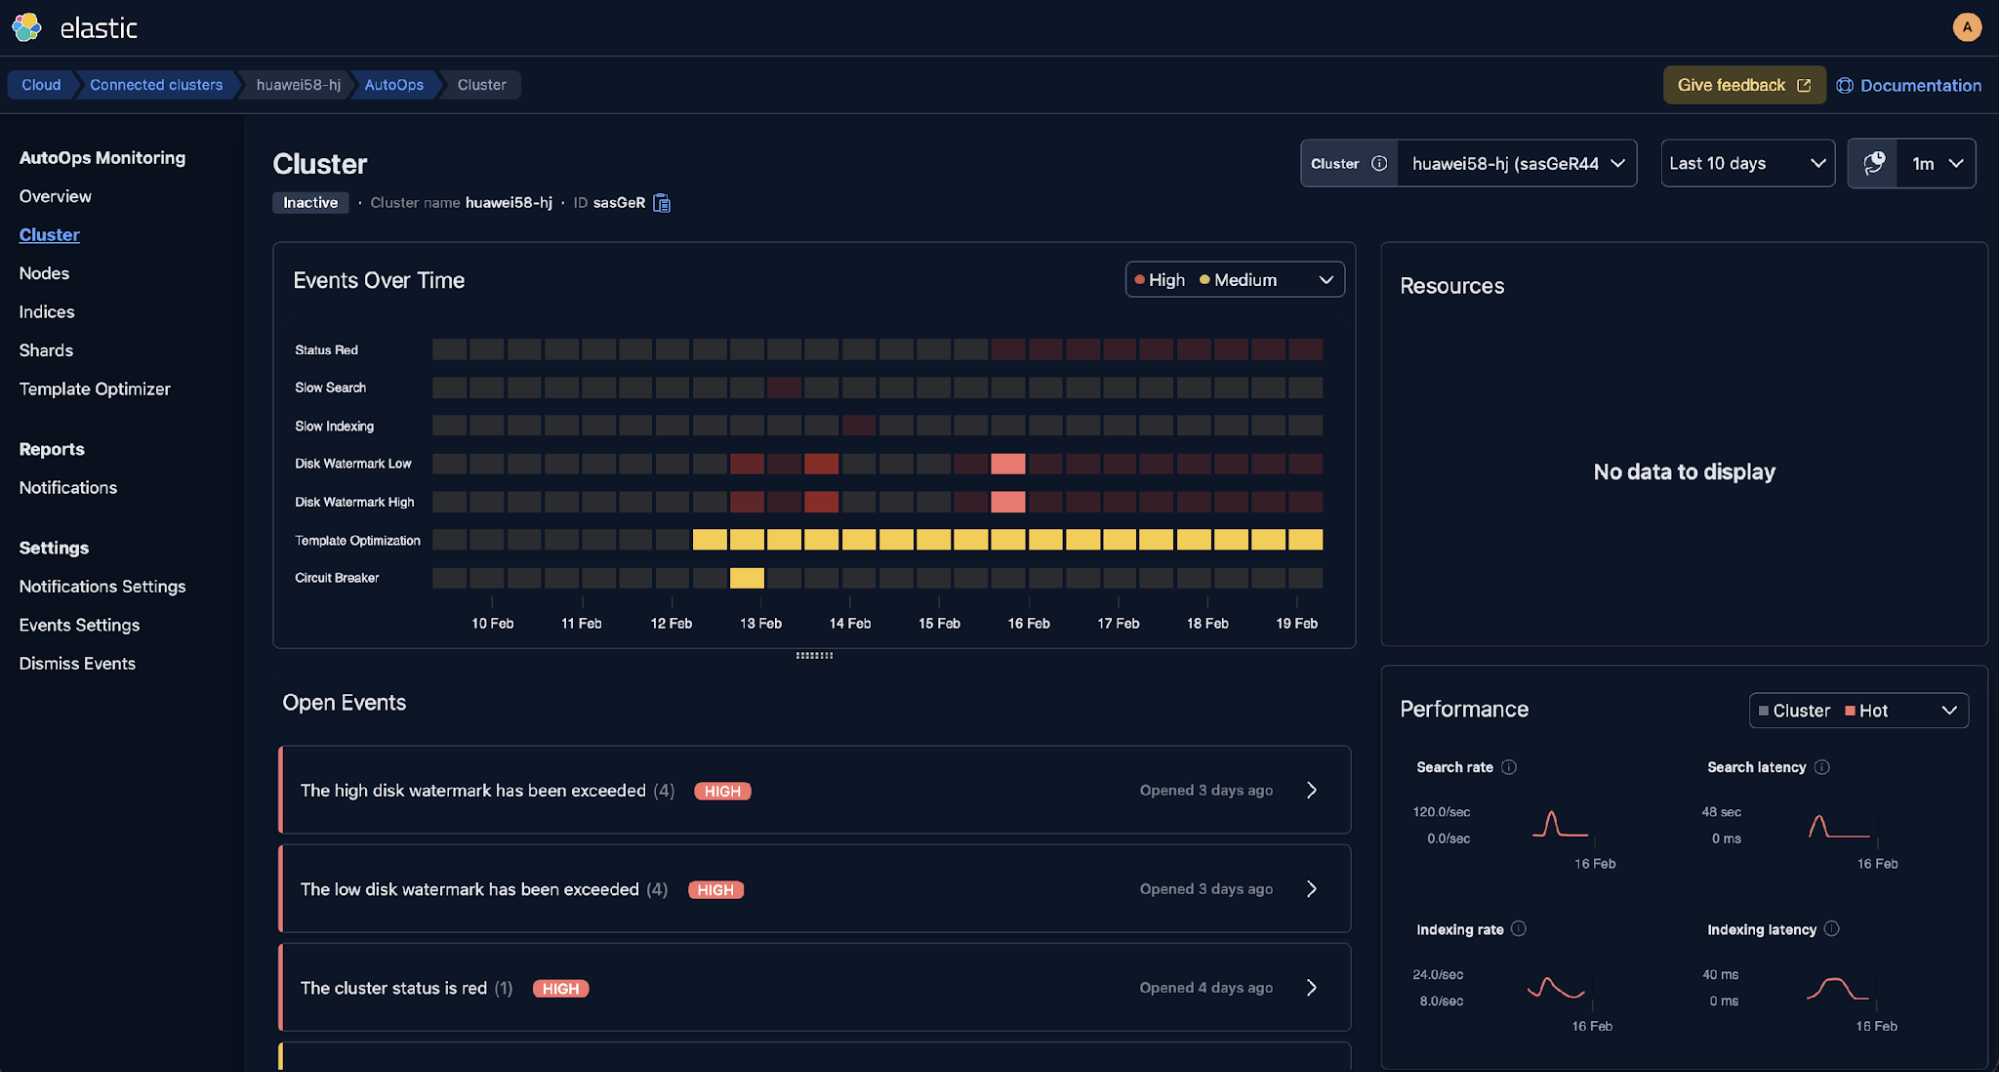
98.9% faster queries, 4x more indexing throughput: a systematic Elasticsearch performance diagnosis
Use AutoOps, the Profile API and ES Rally together to find cluster hotspots, slow queries and index bottlenecks, with real benchmarks showing a 98.9% latency cut and 4x indexing gain.
The disk that never woke up: what actually decided our Qdrant vector search benchmark rematch
On the same hardware, Elasticsearch and Qdrant land in the same range at 56 QPS. The io_uring disk scorer and memory claims turned out to be the two things that mattered least.
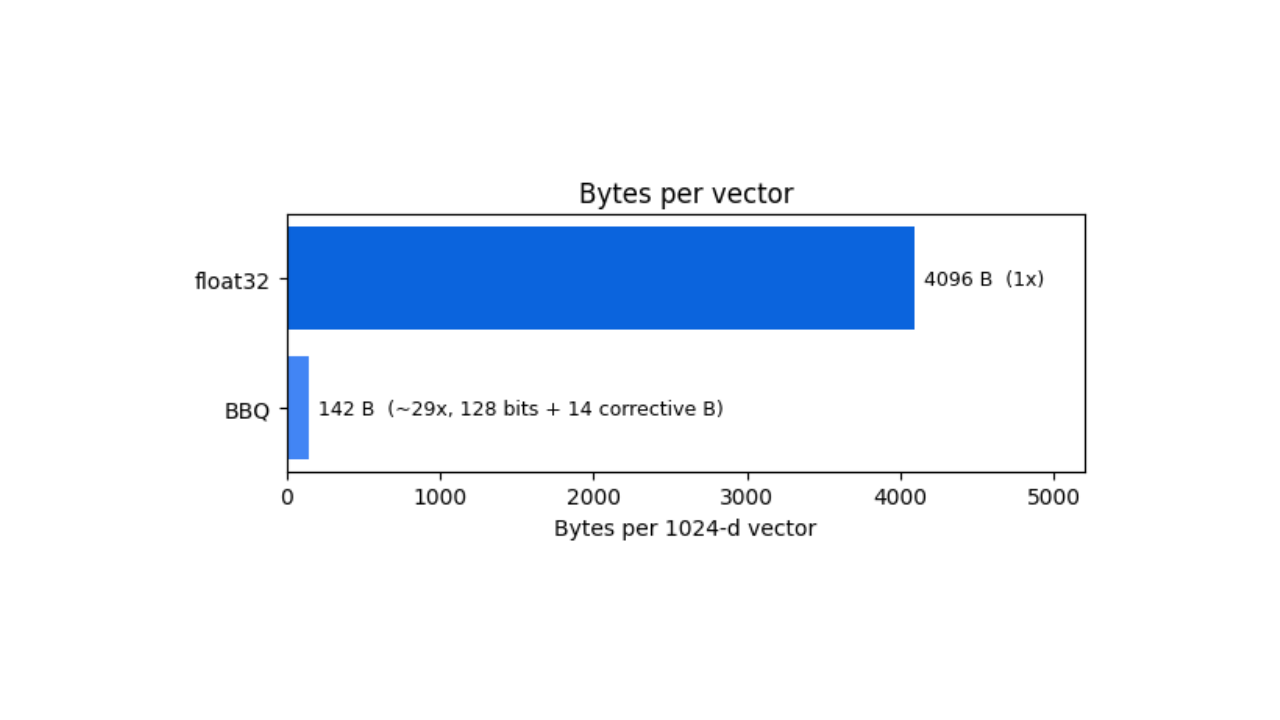
How BBQ shrinks Jina v5 embeddings by 29x without losing recall in Elasticsearch
A hands-on test comparing BBQ and float32 vector indices in Elasticsearch, measuring memory, disk and recall@10 across five languages.
Why Elasticsearch is becoming a columnar database
Elasticsearch is becoming a first-class columnar database. Columnar Mode ships in 9.5, storing data once alongside the existing modes and cutting storage footprints while speeding up analytical queries.